The Blog
Randomness Under Control: Temperature, Top-k, Top-p
SeriesFrom Token to ChatbotEpisode 3 of 3
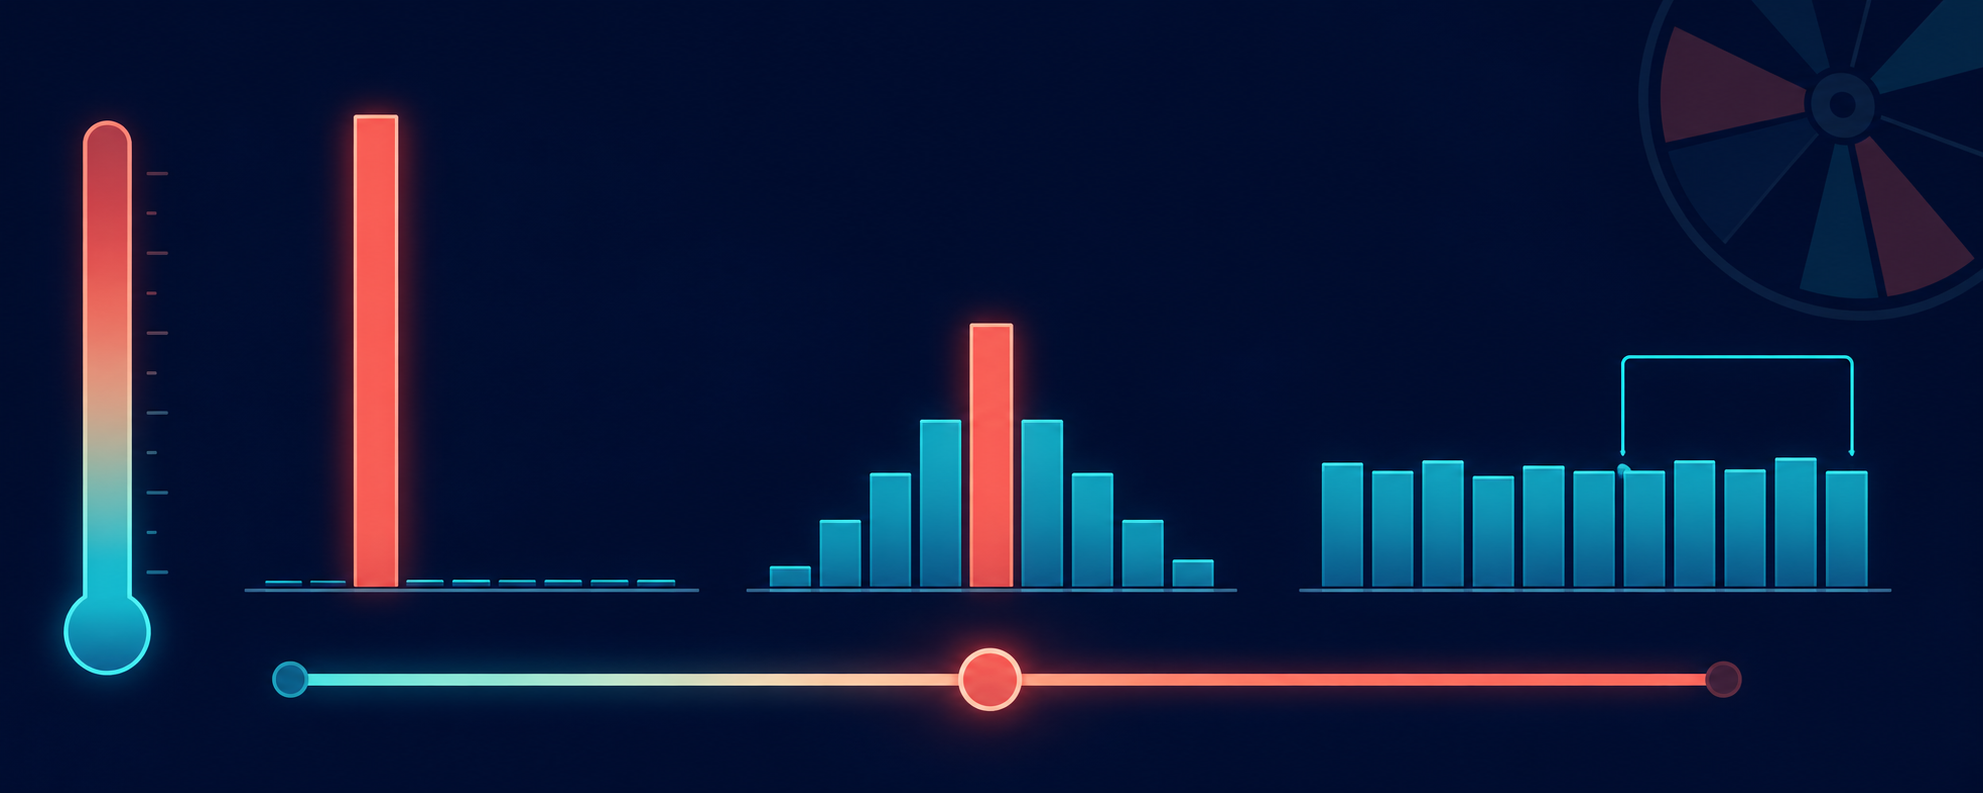
- 🎯 Learning objectives
- 🧭 Prerequisites and setup
- 🗺️ Big picture: where we act today
- PART A — Deterministic or random: why sample
- PART B — Temperature: the creativity dial (THE CORE)
- PART C — Top-k and top-p: filter before drawing
- PART D — Bonus: feel the dials on a real model (GPU optional)
- ⚠️ Common pitfalls (cross-cutting recap)
- 🔁 Final synthetic recap
- ✅ Validation quiz
- 🔧 If you get stuck (troubleshooting)
- 🚀 Going further
Part 3 of the series “From Token to Chatbot” — a hands-on journey from the inner mechanics of an LLM all the way to building your own chatbot.
Since the first episode, one question has been left hanging. You know the model produces a list of probabilities for the next word (episode 1), and you know how it computes that by circulating meaning through attention (episode 2). But we always picked the word with
argmax— “always take the most probable” — which gives a deterministic and often repetitive model. Yet ChatGPT answers you differently every time, with creativity. Today, you discover how the word is actually picked from the list: the three dials — temperature, top-k, top-p — that steer the balance between rigor and creativity. And you’ll feel them from the inside, on your own machine.
📌 Who this is for: you’re coming out of the first two episodes (tokens, embeddings, logits, softmax, attention, the autoregressive loop). The only math tool used today is softmax (episode 2, Part 0.3) — we’ll do a targeted reminder. No heavy new math load.
💻 Hardware prerequisites: the core parts (Parts A to C) run on CPU on any recent computer — we work with small distributions to understand. A bonus Part D (optional) lets you feel the dials on a real modern model (Qwen2.5-1.5B): a CUDA-capable NVIDIA GPU makes it smooth, but it stays doable on CPU (just slower). We stay on
uvand thellm-formationproject.
⏱️ Duration: 2-3 h. Suggested split: Parts A + B in session 1; C + D in session 2. You can stop after Part B (the core).
🎯 Learning objectives
By the end of this module, you’ll be able to:
- Explain the difference between a deterministic choice (
argmax/greedy) and sampling, and why the latter makes a model “creative”. - Describe the effect of temperature on a probability distribution, and predict what T→0 and high T do.
- Distinguish top-k from top-p (nucleus), say what each cuts, and why top-p adapts better.
- Set these parameters in Hugging Face’s
generate()to get a wanted behavior. - Diagnose a generated text (too flat? incoherent?) and know which dial to adjust.
🧠 Keep these 5 objectives in mind. At the end, you’ll come back and tick them off.
🧭 Prerequisites and setup
On the knowledge side: what you learned in the first two episodes, above all that the model’s output is a list of probabilities (via softmax over the logits) and that argmax takes the maximum.
On the tooling side: we reuse the llm-formation project. Move into it:
cd llm-formationFor the core parts (Parts A to C), NumPy is enough (already there from the previous episodes):
uv add numpy # does nothing if already present: normal💡
uvreminder:uv add <package>for a dependency,uv run <script>.pyto run a script in the project’s environment. PyTorch’s GPU build (installed in episode 1, Part D) will serve again in Part D — but only if you have a GPU.
⚠️ Troubleshooting section at the bottom (”🔧 If you get stuck”).
🗺️ Big picture: where we act today
Pipeline reminder. Today, we touch neither the model nor attention: we act only on the very last step, the word choice from the list of probabilities.
   [ ... attention, logits (episodes 1-2) ... ]
              │
              ▼
   [ SOFTMAX ]  ──►  list of probabilities: "Paris" 60%, "Lyon" 8%, "the" 5%, ...
              │
              ▼
   ╔══════════════════════════════╗
   ║  WORD CHOICE                 ║   ◄────  THIS EPISODE, RIGHT HERE
   ║  • greedy (argmax)           ║         how do we draw from the list?
   ║  • temperature               ║         → 3 dials that change everything
   ║  • top-k / top-p             ║
   ╚══════════════════════════════╝
              │
              ▼
   [ the chosen word is re-injected -> we start over (autoregression, episode 1) ]
📌 Today’s idea in one sentence: the list of probabilities doesn’t change; what changes is the drawing rule. Making it more or less “adventurous” amounts to moving a dial between reliability and creativity.
📌 How to read what follows: four parts.
- Part A — deterministic vs random: why sample. Starting point.
- Part B — temperature, the heart of the tuning: you recode it. The core.
- Part C — top-k and top-p: filter before drawing.
- Part D — bonus: feel the dials on a real model (Qwen), on your GPU if you have one.
🧵 Our through-line (continued from the first two episodes): “Paris”
We keep the example. After “The capital of France is”, the model produced a list where “Paris” dominates by far. Today’s question:
Depending on the chosen drawing rule, will we always output “Paris”, or sometimes something else? And on a creative sentence like “Once upon a time”, how do we avoid both flat text AND gibberish?
PART A — Deterministic or random: why sample
A.1 — The reminder: greedy, and its flaw
❓ Opening question: in episode 1,
argmaxalways took the most probable word. What was its observed flaw on “Once upon a time”?
The observation
argmax (the greedy strategy) systematically picks the highest-probability word. Consequences:
- Deterministic: same prompt → exactly the same output, every time.
- Repetitive: you saw it in episode 1, the text goes in circles (“very very very…”), because greedy never allows the slightest deviation and falls back into the same ruts.
For a precise fact (“capital of France”), that’s perfect: we want “Paris”. But to write, tell stories, brainstorm, we want variety. So we need a drawing rule that introduces controlled randomness.
The analogy: the restaurant
Greedy is ordering always your favorite dish, every day, for life. Reliable, but you’ll never discover anything. Sampling is sometimes taking your favorite (often, because you love it), sometimes the #2 on the menu, occasionally a surprise. You keep a preference (loved dishes come up more often) while leaving room for discovery.
A.2 — Sampling: drawing according to the probabilities
❓ Opening question: how do you “draw at random but respecting the probabilities”? If “Paris” is 60% and “Lyon” 8%, how do you output “Paris” more often, without ever fully excluding “Lyon”?
The idea
Sampling is picking a word at random, but with a chance proportional to its probability. “Paris” at 60% will come up ~6 times out of 10; “Lyon” at 8% will come up ~8 times out of 100. We respect the model’s preference without being rigid.
The analogy: the lottery wheel
Imagine a wheel where each word occupies a share proportional to its probability: “Paris” occupies 60% of the wheel, “Lyon” 8%, and so on. We spin the ball: it lands most often on the big shares, sometimes on the small ones. That’s exactly sampling.
🔬 Exercise 1 — greedy vs sampling, on a toy distribution
We build a small list of probabilities and compare the two strategies over 1000 draws. Create j3_manip1_greedy_vs_sampling.py:
# j3_manip1_greedy_vs_sampling.py — compare "always the max" and "weighted random draw"
import numpy as np

words = ["Paris", "Lyon", "the", "France", "banana"]
probs = np.array([0.60, 0.08, 0.05, 0.25, 0.02])   # sum = 1

# --- GREEDY: we always take the index of the maximum probability ---
greedy_choice = words[np.argmax(probs)]
print("GREEDY (argmax) ->", greedy_choice, "(always the same)")

# --- SAMPLING: we draw 1000 times according to the probs, and count ---
draws = np.random.choice(words, size=1000, p=probs)   # p = respects the probabilities
labels, counts = np.unique(draws, return_counts=True)
print("\nSAMPLING over 1000 draws:")
for word, c in sorted(zip(labels, counts), key=lambda x: -x[1]):
    print(f"   {word:8} : {c:4d} times  (~{c/10:.0f} %)")
Run it: uv run j3_manip1_greedy_vs_sampling.py
✅ Checkpoint: greedy always outputs “Paris”. Sampling outputs “Paris” ~600 times, “France” ~250 times, and “banana” only a few times — proportional to the probabilities. You see the fundamental difference: greedy = 1 frozen answer; sampling = variety that respects the model’s preferences. Rerun: the sampling counts change a bit each time (it’s random), greedy never.
✍️ Your turn
- Why does greedy give exactly the same output on every run, while sampling varies?
- Over 1000 draws, roughly how many times should “France” (25%) come up?
- In what concrete case would you prefer greedy, and in what case sampling?
👉 See the answers
- Greedy applies a rule with no randomness: “take the index of the maximum”. For the same list of probabilities, the maximum is always the same, so the choice is too. Sampling draws lots (weighted): the result depends on chance, it varies from one draw to the next.
- About 250 times (25% of 1000). It will rarely be exactly 250: chance makes it fluctuate around that value, the closer the more draws there are.
- Greedy for a factual, deterministic, reproducible answer (info extraction, answering a closed question, code where you want the most probable solution). Sampling for anything needing variety or creativity (writing, brainstorming, natural dialogue).
Mini-summary of Part A
- Greedy (
argmax) = always the most probable → deterministic, but repetitive. - Sampling = draw at random weighted by the probabilities → controlled variety.
- The greedy/sampling choice depends on the need: reliability vs creativity.
PART B — Temperature: the creativity dial (THE CORE)
Raw sampling respects the model’s probabilities. But we want to tune the boldness of the draw: make it more cautious (stick to the very probable words) or more adventurous (give the outsiders their chance). That tuning is temperature. If you keep only one thing from today, it’s this part.
B.1 — The idea: heating or cooling the distribution
❓ Opening question: how do you make a list of probabilities “sharper” (the winner crushes everything) or “more egalitarian” (everyone gets a bit of a chance), without changing the model?
🧮 Targeted math reminder (episode 2, Part 0.3)
Softmax turns scores (logits) into probabilities: exponential of each score, then each divided by the total → shares summing to 100%. Temperature acts just before softmax: we divide each logit by a number T (the temperature) before applying softmax. That’s the whole mechanism.
What T does, concretely
We divide the logits by T, then softmax:
- T = 1: nothing changes, it’s the model’s original distribution.
- T < 1 (e.g. 0.5): we divide by a small number → the logits grow → softmax amplifies the gaps → the distribution becomes sharper (the dominant word crushes the others). We say we “cool down”: more cautious, more deterministic.
- T > 1 (e.g. 1.5): we divide by a large number → the logits move closer → softmax flattens the distribution → the outsiders climb back. We “heat up”: more adventurous, more creative (but a risk of incoherence).
- T → 0: the distribution becomes a spike on the maximum → equivalent to greedy.
📌 Key point: temperature is a creativity dial. Low (0.2-0.7) = reliable, factual, repetitive; medium (~0.8-1.0) = balanced, natural; high (1.2-2.0) = creative, surprising, sometimes incoherent. T→0 = greedy.
The analogy: temperature in the literal sense
Like molecules: cold = they barely move, everything is frozen and ordered (sharp distribution, predictable choice); hot = they get agitated, order blurs (flattened distribution, unpredictable choice). Hence the name “temperature”.
B.2 — Watching temperature deform a distribution
🔬 Exercise 2 — apply temperature by hand
We reuse a toy distribution and watch how T deforms it. Create j3_manip2_temperature.py:
# j3_manip2_temperature.py — the effect of temperature on a distribution
import numpy as np

words  = ["Paris", "France", "the", "Lyon", "banana"]
logits = np.array([3.0,     2.0,     1.0,   0.5,    -1.0])   # the model's raw scores

def softmax(x):
    e = np.exp(x - x.max())
    return e / e.sum()

def with_temperature(logits, T):
    return softmax(logits / T)      # THE core: divide the logits by T, then softmax

for T in [0.1, 0.5, 1.0, 1.5, 3.0]:
    p = with_temperature(logits, T)
    line = "  ".join(f"{w}={pr*100:4.1f}%" for w, pr in zip(words, p))
    print(f"T={T:>3} | {line}")
Run it: uv run j3_manip2_temperature.py
✅ Checkpoint: look at the “Paris” column. At T=0.1, it nears 100% (near-greedy, everything else crushed). At T=1.0, it’s the natural distribution. At T=3.0, the probabilities move closer (“banana” itself climbs back). You literally see the creativity dial at work: lower T = concentration, raise T = dispersion. That’s exactly what an API’s
temperatureparameter does.
🔬 Exercise 3 — the effect on the actually drawn text
Seeing the distribution is good; seeing the text that comes out is better. We sample 20 words at different temperatures. Create j3_manip3_temp_on_draw.py:
# j3_manip3_temp_on_draw.py — same probs, draws at different temperatures
import numpy as np

words  = ["Paris", "France", "the", "Lyon", "banana"]
logits = np.array([3.0, 2.0, 1.0, 0.5, -1.0])

def softmax(x):
    e = np.exp(x - x.max()); return e / e.sum()

for T in [0.3, 1.0, 2.0]:
    p = softmax(logits / T)
    draw = np.random.choice(words, size=20, p=p)   # 20 draws at this temperature
    print(f"T={T} -> {' '.join(draw)}")
Run it: uv run j3_manip3_temp_on_draw.py
✅ Checkpoint: at T=0.3, the sequence is heavily dominated by “Paris” (little variety). At T=1.0, a reasonable mix. At T=2.0, “banana” and “Lyon” appear often (variety… but also nonsense). On a real model, that’s exactly the trade-off you’ll adjust: too low = boring, too high = incoherent.
🧵 “Paris” — a first piece of the answer
On our through-line: at low temperature, “The capital of France is” will output almost always “Paris” (what we want for a fact). Raising the temperature would bring “Lyon” or others back up — useless, even wrong, for a factual question. Lesson: for facts, low temperature; keep the dial high for creativity. The second half of the question (avoiding flat AND gibberish on “Once upon a time”) will find its answer in Part C with top-k/top-p.
✍️ Your turn
- Without running: at very low T (0.1), which episode-1 strategy does sampling become equivalent to?
- You generate a story and the text is flat, predictable, repetitive. Do you raise or lower the temperature?
- Your model produces incoherent gibberish. Which way do you adjust the temperature?
👉 See the answers
- Greedy (
argmax). When T→0, softmax concentrates all the probability on the maximum logit: drawing “at random” from a distribution that’s ~100% on a single word amounts to always choosing that word. - You raise the temperature. Flat text comes from a distribution too concentrated on the obvious words: heating gives the less probable words their chance and introduces variety.
- You lower the temperature. Gibberish often comes from a distribution too flattened where improbable words get drawn: cooling reconcentrates the draw on coherent choices.
Mini-summary of Part B
- Temperature divides the logits before softmax: it deforms the distribution.
- Low T = sharp (reliable, repetitive); high T = flat (creative, risky); T→0 = greedy.
- It’s the main “reliability ↔ creativity” dial of a model.
PART C — Top-k and top-p: filter before drawing
Temperature deforms the whole distribution, but leaves a gap: even flattened, it keeps a small chance of drawing an absurd word (the long tail of very improbable words). Top-k and top-p fix that by cutting the bad candidates before the draw. An important part, but you can save it for a 2nd session.
C.1 — Top-k: keep only the k best
❓ Opening question: if a model hesitates between 50,000 words but only 5 are relevant, should we leave a chance to the other 49,995?
The idea
Top-k: we keep only the k most probable words, set the others to zero, then renormalize (so the remaining k sum to 100%) and draw among them. With k=5, only the 5 best candidates are eligible; the long tail of absurdities is eliminated outright.
The analogy: the shortlist
Like a jury that keeps only the 5 best candidates before the final interview. The other 49,995 are dropped from the start — no point leaving them a residual chance.
🔬 Exercise 4 — top-k by hand
Create j3_manip4_topk.py:
# j3_manip4_topk.py — keep only the k best, then renormalize
import numpy as np

words = ["Paris", "France", "the", "Lyon", "banana", "xyz"]
probs = np.array([0.50, 0.25, 0.10, 0.08, 0.05, 0.02])

def top_k(probs, k):
    sorted_idx = np.argsort(probs)[::-1]     # indices from most to least probable
    keep = sorted_idx[:k]                    # we keep the first k
    filtered = np.zeros_like(probs)
    filtered[keep] = probs[keep]             # the others stay at 0
    return filtered / filtered.sum()         # renormalization -> sum = 1

for k in [1, 2, 3]:
    p = top_k(probs, k)
    line = "  ".join(f"{w}={pr*100:4.1f}%" for w, pr in zip(words, p))
    print(f"k={k} | {line}")
Run it: uv run j3_manip4_topk.py
✅ Checkpoint: at k=1, all the probability goes to “Paris” (greedy equivalent). At k=2, only “Paris” and “France” remain, renormalized between the two (~67%/33%). The absurd words (“xyz”, “banana”) are eliminated as soon as they fall outside the top-k. You see the filter cut the long tail.
The limit of top-k
k is fixed, but situations vary. After “The capital of France is”, only one word is correct (“Paris”): k=5 lets 4 bad candidates through. After “I feel”, dozens of words are plausible: k=5 cuts too many. A fixed k doesn’t adapt to whether the model is sure or hesitant. Hence top-p.
C.2 — Top-p (nucleus): keep just enough mass
❓ Opening question: instead of fixing the number of candidates, can we fix the amount of probability to cover, and let the number adjust on its own?
The idea
Top-p (also called nucleus sampling): we keep the most probable words until their cumulative probability reaches p (e.g. p=0.9 = 90%), then discard the rest, renormalize, and draw. The number of kept words adapts:
- sure model (“Paris” at 95%) → 1 word is enough to reach 90%,
- hesitant model (spread-out probabilities) → many are needed.
The analogy: filling a basket up to a threshold
You add candidates from most to least probable, cumulating, and stop as soon as the basket holds 90% of the probability “mass”. Depending on the case, the basket holds 1 or 30 words — it adjusts to the model’s confidence.
🔬 Exercise 5 — top-p by hand
Create j3_manip5_topp.py:
# j3_manip5_topp.py — keep words until reaching p% of cumulative probability
import numpy as np

def top_p(words, probs, p):
    idx = np.argsort(probs)[::-1]            # from most to least probable
    cumulative = 0.0
    keep = []
    for i in idx:
        keep.append(i)
        cumulative += probs[i]
        if cumulative >= p:                  # as soon as we reach threshold p, we stop
            break
    filtered = np.zeros_like(probs)
    filtered[keep] = probs[keep]
    return filtered / filtered.sum(), [words[i] for i in keep]

# Case 1: SURE model (one word dominates)
words1 = ["Paris", "France", "the", "Lyon", "banana"]
p1     = np.array([0.92, 0.04, 0.02, 0.01, 0.01])
_, kept1 = top_p(words1, p1, 0.9)
print("Sure model,     p=0.9 -> kept words:", kept1)

# Case 2: HESITANT model (spread-out probabilities)
words2 = ["a", "b", "c", "d", "e", "f"]
p2     = np.array([0.25, 0.22, 0.20, 0.15, 0.10, 0.08])
_, kept2 = top_p(words2, p2, 0.9)
print("Hesitant model, p=0.9 -> kept words:", kept2)
Run it: uv run j3_manip5_topp.py
✅ Checkpoint — the key point of this part: in the “sure” case, top-p keeps only 1 word (“Paris” already covers 92% ≥ 90%). In the “hesitant” case, it keeps 5 to reach 90%. The same setting p=0.9 adapts automatically to the model’s confidence — which top-k, with its fixed k, cannot do. That’s why top-p is the most used setting in practice.
🧵 “Paris” — the complete answer to our through-line
We can now fully answer today’s question. On “The capital of France is” (sure model), top-p keeps only “Paris”: we never draw an absurdity, even with sampling. On “Once upon a time” (hesitant model), top-p widens the basket: variety, but bounded to plausible words — so neither flat nor gibberish. In practice, we combine temperature (amount of creativity) and top-p (anti-absurdity guardrail): that’s the recipe that avoids both pitfalls.
✍️ Your turn
- In one sentence, what is the fundamental difference between top-k and top-p?
- Very sure model (“Paris” at 95%). With p=0.9, how many words does top-p keep? And top-k with k=5?
- Why do we often combine temperature and top-p, rather than one or the other?
👉 See the answers
- Top-k keeps a fixed number of words (the k best) whatever the situation; top-p keeps a variable number of words, just enough to cover an amount of probability p — it adapts to the model’s confidence.
- Top-p keeps only 1 word (“Paris” at 95% already exceeds 90%). Top-k with k=5 keeps 5 words, including 4 bad candidates that shouldn’t have stayed — hence its rigidity.
- Because they play complementary roles: temperature sets the amount of creativity (how much we flatten the distribution), while top-p sets a guardrail that eliminates the long tail of absurdities. Together: controlled creativity without incoherent drift.
Mini-summary of Part C
- Top-k: keep the k best (fixed number), discard the rest, renormalize.
- Top-p (nucleus): keep just enough words to cover p % (variable number, adapts).
- We often combine temperature + top-p: adjustable creativity + anti-absurdity guardrail.
PART D — Bonus: feel the dials on a real model (GPU optional)
So far, on toy distributions on CPU. Now the satisfying moment: we reuse the modern model seen in episode 1 (Qwen2.5-1.5B) and vary temperature / top-k / top-p on real generations. You’ll feel, on real text, what each dial changes. If you have a CUDA-capable NVIDIA GPU, it’s smooth; otherwise, it runs on CPU — slower, so lower
max_new_tokensto keep trials quick.
D.1 — Nothing new to install
We reuse transformers + torch and the Qwen model already downloaded in episode 1. If you have a GPU, check it if needed:
uv run manip5_gpu_check.py # should print: CUDA available: True💡 If
transformersis no longer listed,uv add transformers. The Qwen model is cached since episode 1: no re-download. Without a GPU, ignore the check — the code falls back to CPU on its own.
D.2 — Temperature on a real model
We generate the same sequence at three temperatures and compare. Create j3_manip6_temp_real.py:
# j3_manip6_temp_real.py — temperature on real generations (Qwen)
from transformers import AutoModelForCausalLM, AutoTokenizer
import torch

device = "cuda" if torch.cuda.is_available() else "cpu"
dtype = torch.float16 if device == "cuda" else torch.float32   # float16: GPU; float32: CPU
name = "Qwen/Qwen2.5-1.5B-Instruct"
tok = AutoTokenizer.from_pretrained(name)
model = AutoModelForCausalLM.from_pretrained(name, torch_dtype=dtype).to(device)

messages = [{"role": "user", "content": "Write the opening of a fairy tale, in one sentence."}]
inputs = tok.apply_chat_template(messages, add_generation_prompt=True, return_tensors="pt").to(device)

for T in [0.2, 0.8, 1.5]:
    out = model.generate(
        inputs,
        max_new_tokens=60,
        do_sample=True,          # do_sample=True = we SAMPLE (otherwise greedy)
        temperature=T,           # our dial of the day
        top_p=1.0, top_k=0,      # neutralize top-p/top-k to isolate the temperature effect
    )
    text = tok.decode(out[0][inputs.shape[1]:], skip_special_tokens=True)
    print(f"\n=== T={T} ===\n{text}")
Run it: uv run j3_manip6_temp_real.py
✅ Checkpoint: at T=0.2, the fairy-tale opening is tame, conventional, almost always the same if you rerun. At T=0.8, it gets livelier and more varied. At T=1.5, it heads in surprising directions — sometimes brilliant, sometimes shaky. You feel, on real text, the reliability/creativity trade-off you were manipulating abstractly in Part B. Rerun several times: at low T, little variety between runs; at high T, a lot.
D.3 — top-p in action
We fix a lively temperature and show that top-p bounds the drift. Create j3_manip7_topp_real.py:
# j3_manip7_topp_real.py — top-p as a guardrail at high temperature
from transformers import AutoModelForCausalLM, AutoTokenizer
import torch

device = "cuda" if torch.cuda.is_available() else "cpu"
dtype = torch.float16 if device == "cuda" else torch.float32
name = "Qwen/Qwen2.5-1.5B-Instruct"
tok = AutoTokenizer.from_pretrained(name)
model = AutoModelForCausalLM.from_pretrained(name, torch_dtype=dtype).to(device)

messages = [{"role": "user", "content": "Give an original name idea for a coffee shop."}]
inputs = tok.apply_chat_template(messages, add_generation_prompt=True, return_tensors="pt").to(device)

for p in [1.0, 0.9, 0.5]:
    out = model.generate(
        inputs, max_new_tokens=40, do_sample=True,
        temperature=1.3,         # deliberately high temperature
        top_p=p,                 # we vary the guardrail
    )
    text = tok.decode(out[0][inputs.shape[1]:], skip_special_tokens=True)
    print(f"\n=== top_p={p} (T=1.3) ===\n{text}")
Run it: uv run j3_manip7_topp_real.py
✅ Checkpoint: at top_p=1.0 (no filter) and T=1.3, the output can drift (off-topic words). At top_p=0.9, it stays creative but coherent. At top_p=0.5, it tightens onto the safest ideas. You see the guardrail work: top-p cuts the long tail of absurdities the high temperature would have let through. It’s the winning combination of Part C, on a real model.
💡 If you have a GPU, watch it in a second terminal:
watch -n 1 nvidia-smi. Samedevice+.to(device)reflex as the previous episodes. The sampling parameters cost almost nothing: it’s the model that works, not the draw. Without a GPU, everything runs on CPU (slower).
✍️ Your turn
- In
generate(), what isdo_sample=Truefor? What happens if you set it toFalse(test it)? - You want factual and reproducible answers (e.g. an assistant answering closed questions). Which settings do you choose (do_sample, temperature)?
- Reuse
j3_manip6with the prompt “Explain what a token is.” at T=0.2 then T=1.5. For a technical explanation, which temperature do you prefer and why?
👉 See the answers
do_sample=Trueenables sampling (weighted draw, so temperature/top-p/top-k apply). Withdo_sample=False,generate()reverts to greedy (argmax): deterministic output, and the temperature/top-p parameters are ignored. Testing it, you always get the same generation.do_sample=False(greedy) ordo_sample=Truewith a low temperature (e.g. 0.2). For reproducible facts, greedy is the safest: same question → same answer, and we take the most probable word.- For a technical explanation, low T (0.2): we want precision and coherence, not fantasy. At T=1.5, the explanation risks drifting into imprecise or wrong phrasings. Creativity is useful for writing, not for explaining a fact.
Mini-summary of Part D
- In
generate():do_sample=Trueenables sampling;temperature,top_p,top_ktune it. - On a real model, low T = reliable, high T = creative, top-p = guardrail against drift.
- Usual recipe: do_sample=True + moderate temperature + top_p ~0.9 for controlled creativity; greedy or low T for facts.
⚠️ Common pitfalls (cross-cutting recap)
| Pitfall | Why it’s dangerous | The right reflex |
|---|---|---|
Forgetting do_sample=True then setting temperature | Without sampling, temperature is ignored (greedy) | For T/top-p to act: do_sample=True |
| Believing temperature changes the model | It touches only the final distribution | T deforms the list of probabilities, nothing else |
| Raising temperature for “more intelligence” | High T = more randomness, not more accuracy | High T = creativity/risk, not factual quality |
| Confusing top-k and top-p | k = fixed number; p = variable mass | top-p adapts to the model’s confidence |
| Setting top-p=1.0 with very high T | No guardrail → risk of gibberish | Pair a lively T with a top-p ~0.9 |
| Hunting for THE universal perfect value | The right setting depends on the task | Factual → low; creative → higher; you adjust |
Running the exercises without uv run | ModuleNotFoundError / wrong environment | Always uv run <script>.py from llm-formation/ |
🔁 Final synthetic recap
   THE LIST OF PROBABILITIES DOESN'T CHANGE — ONLY THE DRAWING RULE CHANGES
                                    │
     ┌──────────────┬──────────────┴──────────────┬──────────────┐
     ▼              ▼                              ▼              ▼
  PART A         PART B                         PART C         PART D
 greedy vs       TEMPERATURE                    top-k / top-p  on a real
 sampling        (the core)                     (guardrails)   model (Qwen)
     │              │                              │              │
 argmax =        logits / T  then softmax        k = FIXED      do_sample=True
 deterministic   low T  -> sharp (reliable)      number         temperature
 sampling =      high T -> flat (creative)       p = VARIABLE   top_p ~0.9
 weighted draw   T→0    -> greedy                mass (adapts)  = winning combo

   Recipe: factual -> greedy / low T ;  creative -> moderate T + top_p ~0.9
💻 Part D (bonus): on your GPU (or CPU), with Qwen, you felt the dials on real text — low T tame, high T surprising, top-p as a guardrail. Same settings as the APIs you’ll meet later in the series.
🧠 Self-assessment (actually do it): without rereading, can you (a) say what T→0 does and why, (b) explain the top-k / top-p difference in one sentence, and (c) give the settings for a factual answer vs a creative story? If a point sticks, go back to the relevant part before the quiz.
✅ Validation quiz
- What is the difference between greedy and sampling, and why does the latter make a model “creative”?
- What does temperature T=0.3 do to a distribution? And T=2.0? Which strategy does T→0 amount to?
- Explain the difference between top-k and top-p, and why top-p adapts better to the model’s confidence.
- In
generate(), why does settingtemperaturewithoutdo_sample=Truehave no effect? - Your model generates flat, repetitive text, then (after tuning) incoherent gibberish. Which dial did you move, and which way each time?
👉 See the answer key
- Greedy always takes the most probable word → deterministic and repetitive output. Sampling draws a word at random weighted by the probabilities → it introduces variety. This controlled variety (probable words come up more often, but not always) produces the “creativity” effect: the model explores different continuations on each generation.
- T=0.3 (< 1) amplifies the gaps: the distribution becomes sharper, the dominant word crushes the others (more reliable, more repetitive). T=2.0 (> 1) flattens the distribution: the outsiders climb back (more creative, more risky). T→0 amounts to greedy (all the probability concentrates on the maximum).
- Top-k keeps a fixed number of words (the k best), regardless of the situation. Top-p keeps just enough words to cover an amount of probability p, so a variable number. Top-p adapts better because, when the model is sure, it keeps only one word, and when it hesitates, it keeps many — whereas a fixed k lets absurdities through or cuts too much, depending on the case.
- Because without
do_sample=True,generate()does greedy (it takes the argmax). Temperature only deforms a distribution before a random draw; if there’s no draw, the deformation has no observable effect. You must enable sampling for temperature (and top-p/top-k) to count. - Flat text → I raised the temperature (distribution too concentrated: heating adds variety). Then gibberish → the temperature was too high: I lower it (distribution too flattened drawing incoherent words: cooling reconcentrates). The right setting is a balance between the two, often with a top-p ~0.9 as a guardrail.
🧠 Objectives check: revisit the 5 objectives from the start. For each, can you say “yes, I can do it”? If a single one resists, you know which section to reread.
🔧 If you get stuck (troubleshooting)
“Setting temperature changes nothing.”
You probably forgot do_sample=True: without it, generate() does greedy and ignores temperature. Add it.
“uv run: ModuleNotFoundError (numpy / transformers).”
Missing dependency or running without uv run. From llm-formation/, redo uv add <package> and run with uv run <script>.py.
“torch.cuda.is_available() returns False.”
CPU version of torch — not a problem: Parts A-C run on CPU, and Part D too (slower). If you want an NVIDIA GPU, reinstall the GPU version (episode 1, Part D): uv add torch --index pytorch-cuda=https://download.pytorch.org/whl/cu124, then re-check with uv run manip5_gpu_check.py.
“The Qwen generations are slow.”
On GPU, the first generation after loading has some latency (setup), then it’s fast; check the model is on GPU and loaded in float16. On CPU, it’s normally slow: lower max_new_tokens (e.g. 20-30) and the number of tested values to keep trials short.
“A warning on temperature/top_p when do_sample=False.”
Normal: transformers warns that these parameters have no effect in greedy. Ignore it, or set do_sample=True.
“Warning about the attention mask / pad token.” Benign for our uses. If the script produces its text, ignore it.
💡 General reflex: paste the exact error message into a search engine. And come back to me if needed.
📌
uvcommand memo for the day:
cd llm-formation— move into the projectuv add numpy transformers— the day’s dependenciesuv run <script>.py— run a script- (GPU option, if you have one)
uv add torch --index pytorch-cuda=https://download.pytorch.org/whl/cu124
🚀 Going further
🔄 Another approach (same subject, different angle)
| Resource | Type | How the angle differs | Effort |
|---|---|---|---|
| Hugging Face — “How to generate text” (blog huggingface.co) | Article + code | THE reference tutorial on greedy/beam/top-k/top-p, with runnable examples | Reading + practice |
| ”The Curious Case of Neural Text Degeneration” (arxiv.org/abs/1904.09751) | Research paper | The paper that introduced top-p (nucleus): why the long tail degrades text | Demanding reading |
| OpenAI / Anthropic — API parameters docs (platform.openai.com / docs.anthropic.com) | Official docs | See temperature/top-p on the API side, as you’ll use them later in the series | Reading |
🧩 Complementary (widen the scope)
| Resource | Type | The concrete link with today | Effort |
|---|---|---|---|
transformers docs — GenerationConfig (huggingface.co/docs) | Official docs | All the generate() parameters: beam search, repetition_penalty, etc. | Reading |
| ”Repetition penalty” and anti-repetition (HF blog) | Article | Other levers against repetitive text, beyond temperature | Reading |
| Prompt playgrounds (platform.openai.com/playground) | Web tool | Move temperature/top-p live on a real model, without coding | To play with |
🔬 Deep dive (dig into the subject itself)
| Resource | Type | Level / prerequisites | Effort |
|---|---|---|---|
| Andrej Karpathy — “Let’s build GPT” (generation section) | Video + code | Intermediate; implements sampling with temperature inside the loop | Practice |
| ”Locally Typical Sampling”, “Mirostat” (arxiv) | Papers | Advanced; sampling methods beyond top-k/top-p | Demanding reading |
transformers docs — Streaming (huggingface.co/docs) | Docs | Generate token by token live (useful for the chatbot that closes the series) | Reading + practice |
📈 Suggested learning sequence
- Today first: do exercises 1-3 (greedy vs sampling, then temperature) until you see the distribution deform. That’s the click.
- Do Part C (top-k/top-p) and remember above all why top-p adapts (exercise 5, sure vs hesitant case).
- Do Part D: feeling the dials on Qwen anchors everything else.
- Read the HF blog “How to generate text” to consolidate, then skim the nucleus paper if you want the depth.
- Keep the OpenAI/Anthropic playground handy: it’s the direct bridge to the APIs coming later in the series.
➡️ Next episode — Serving a model locally: you now understand the full pipeline of an LLM, from input to tuned generation (the first three episodes). It’s time to leave the toy scripts and run real models cleanly on your own machine. Next episode: installing and serving local models (via Hugging Face and an OpenAI-compatible server), to prepare the first API calls that follow. Your GPU will finally show its full potential (and light models stay playable on CPU). Come back with your exercises done and your questions.